
Large environment
Large environments typically introduce significantly more variables, including multiple sites, clusters, storage systems, backup destinations, and concurrent workloads.
This blueprint should therefore be treated as a reference architecture and starting point for design, rather than a fixed sizing recommendation. Large deployments should always be validated and adjusted to the specific customer environment.
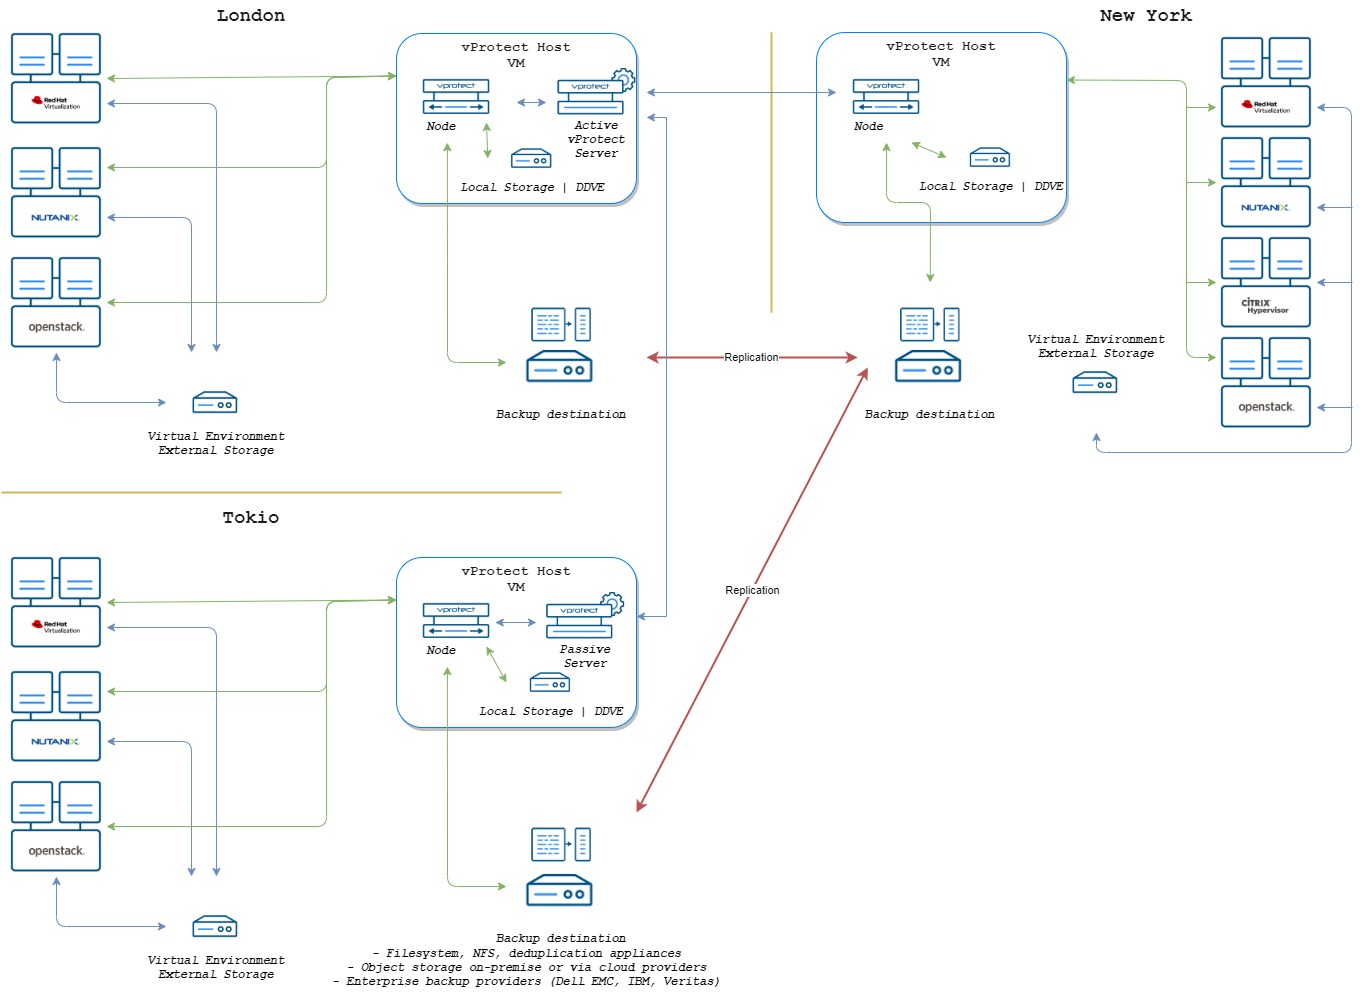
Recommended configuration
Network: minimum 10 Gb/s
Number of sites: 1 or more
Storware Backup & Recovery installations: 1 or more, depending on the environment design
Deployment model: 2 Server instances and at least 2 dedicated Nodes
Resources: start from 8 vCPU and 16 GB RAM for data-processing components and adjust based on workload
Concurrent backup threads: up to 10 per Node
Backup window: approximately 12 hours
Data processed during the backup window: 25 TB or more
Staging space per Node:
LargestProtectedVM × NumberOfConcurrentBackupThreads
Architecture considerations
At this scale, sizing cannot be based on data volume alone. The architecture should also consider:
number and location of protected environments,
number of clusters and storage providers,
backup method used by each platform,
source storage performance,
network topology and available bandwidth,
backup destination performance,
required backup and recovery windows,
expected concurrency,
staging requirements,
high-availability requirements.
Depending on these factors, additional Nodes or separate Storware Backup & Recovery installations may be required.
Network considerations
A minimum 10 Gb/s network is recommended, but large environments may require substantially more aggregate bandwidth.
The effective throughput should be measured across the complete backup path:
Source → Node → Staging → Backup Destination
When multiple Nodes operate simultaneously, both the network and backup destination must be capable of sustaining their combined throughput.
For multi-site environments, bandwidth and latency between sites should be evaluated separately.
Backup concurrency
As a general guideline, a Node can be configured with up to 10 concurrent backup tasks.
However, the optimal concurrency level depends on the protected platform and infrastructure. Increasing the number of tasks may not improve overall throughput if the source storage, network, or backup destination becomes saturated.
For large environments, concurrency should therefore be determined through representative performance testing rather than by Node capacity alone.
Additional Nodes should be introduced when required to:
distribute backup workload,
support multiple clusters or sites,
increase aggregate throughput,
isolate workloads from different platforms,
meet backup window requirements.
Staging space
Staging space should be calculated separately for each Node:
StagingSpacePerNode = LargestProtectedVM × NumberOfConcurrentBackupThreads
For example, if the largest protected VM is 2 TB and the Node processes 10 exports concurrently:
2 TB × 10 = 20 TB
This provides a conservative starting point. Actual staging requirements depend on how quickly exported data is transferred to the backup destination.
In large environments, additional capacity should be considered to accommodate temporary performance differences between export and store operations.
Server and Node resources
Resource requirements should be calculated based on the total number of concurrent tasks rather than environment size alone.
For large deployments, 8 vCPU and 16 GB RAM can be used as an initial planning baseline for data-processing components, but additional resources may be required depending on concurrency and backup methods.
Where possible, Server and Node roles should be separated to allow independent scaling.
Nodes can then be added as required without increasing the load on the Server component.
Multi-site environments
For environments spanning multiple sites, consider whether Nodes should be deployed locally at each site.
Local Nodes can help:
avoid transferring backup traffic across WAN links,
reduce dependency on inter-site connectivity,
distribute staging and processing workloads,
improve scalability.
Separate Storware Backup & Recovery installations may also be appropriate where sites require operational or infrastructure independence.
Last updated